Blogs
AI Data Pipelines for Messy Enterprise Data: A Practical Guide for FDEs
AI Data Pipelines for Messy Enterprise Data: A Practical Guide for FDEs
By
R&D, FDE Academy
October 9, 2026

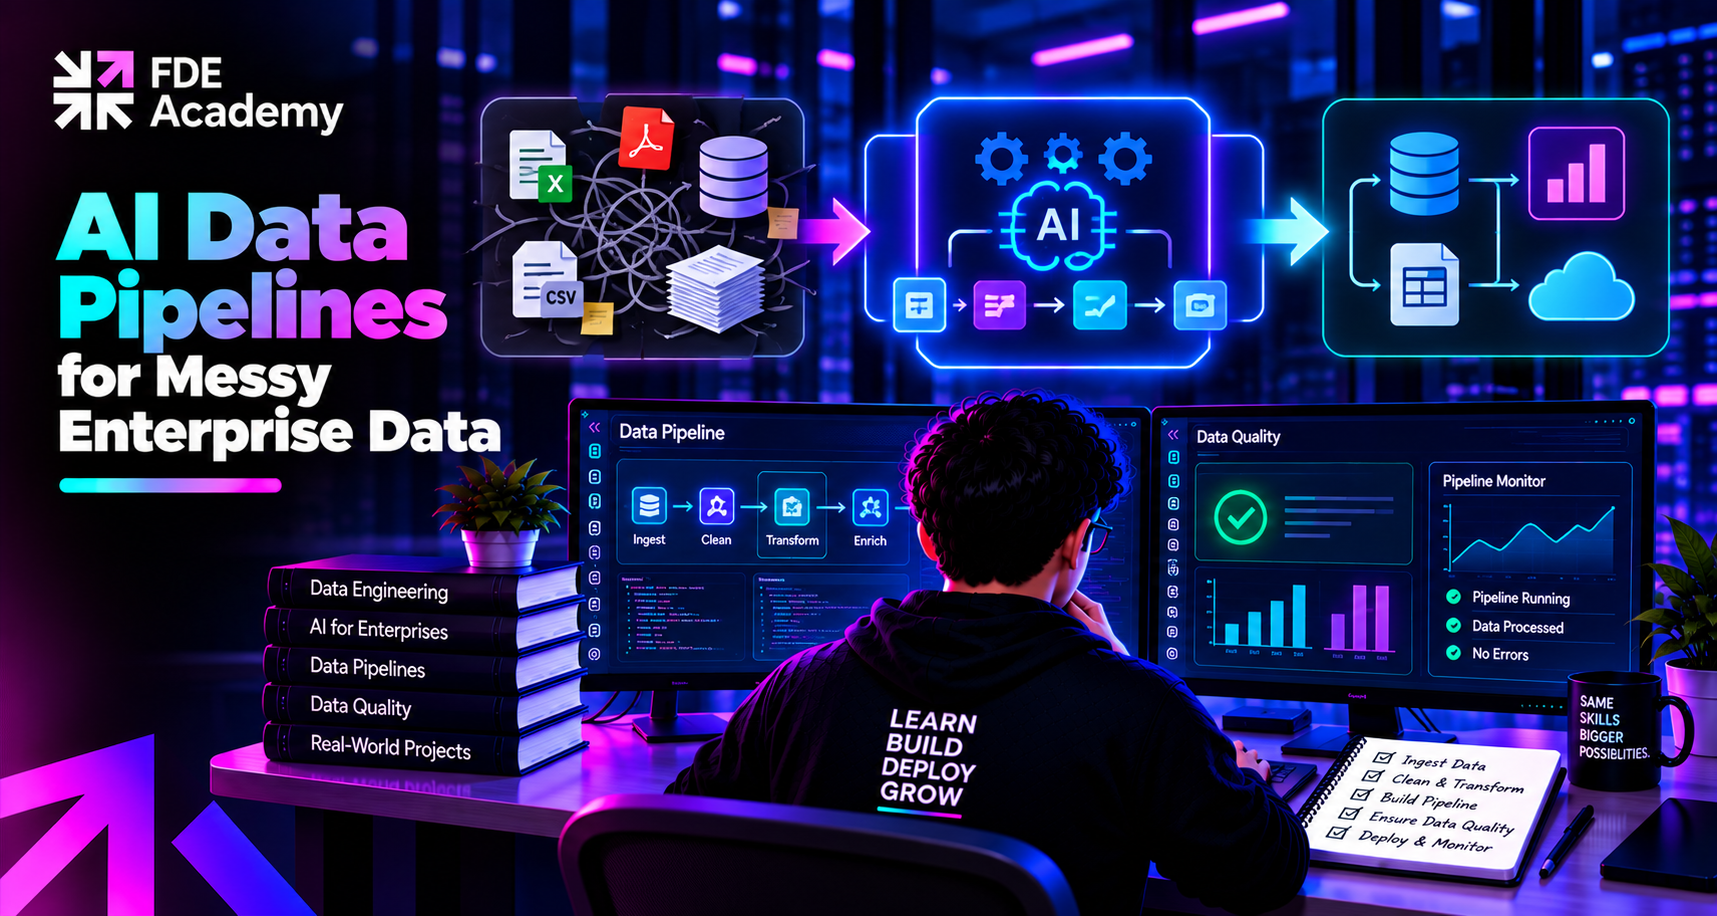
In demos, the data is clean. In customer environments, it lives in decades-old systems, shared drives, email attachments, spreadsheets with merged cells, and documents that contradict each other. An FDE learns quickly that data integration usually matters more than which model is chosen. The high-level picture is covered in how FDEs build enterprise AI platforms; this article goes one level down, into the pipeline itself.
The pattern is consistent. A retrieval-based assistant gives a wrong answer. The team tweaks the prompt, then swaps the model. The problem persists, because the answer was wrong before the model ever saw it: the retrieved passage came from an outdated policy, a mangled table, or a chunk that cut a sentence in half. Practitioners who debug these failures recommend working bottom-up: check the data layer first, then retrieval, then the prompt, then generation. Most production failures trace back to the data. It is a recurring theme in why AI projects fail and how FDEs fix it.
An AI data pipeline is the set of automated steps that collects data from source systems, converts it into clean, structured, well-labelled form, and delivers it to an AI system, such as a retrieval index, a feature store, or an agent's tools, in a way that stays current and respects access rules. It is the data engineering behind an AI feature.
It is related to a traditional ETL or ELT pipeline but has extra concerns. Much of the input is unstructured text. Quality problems show up as confident wrong answers rather than failed jobs. Permissions have to travel with the data. And the "consumer" is a model that can't ask a clarifying question.
"Messy" is not one problem. Naming the specific kinds helps you choose the right fix.
Before writing code, find out what data exists, who owns it, how it is accessed, and how it is really used. Interview people who do the work; the documented process and the real one are often different. Map which sources are authoritative for which facts. This is the data side of discovery in the FDE project lifecycle, and it often reveals that the data is more fragmented and poorly documented than anyone expected.
Connect to sources through connectors or APIs and pull content along with stable identifiers, source locations, timestamps, and access attributes. Every chunk later in the pipeline should trace back to a source object and the permissions attached to it. Dropping permissions at this stage is the most expensive mistake to fix later.
Decide early what should be ingested in bulk and what should be queried live. Some data is better accessed through a live connection than copied into an index, which is where patterns like MCP for forward deployed engineers come in.
Parsing converts files into structured elements such as titles, paragraphs, lists, tables, and images. Treat parsing quality as a first-class constraint, because errors like misordered text or dropped table cells carry through every later stage. Use OCR for scans and layout-aware extraction for tables, and keep table row and column relationships intact. Spot-check parsed output against the originals by eye; it is tedious and it catches problems nothing else will.
Remove boilerplate such as headers, footers, and navigation, standardise dates, units, and encodings, and fix obvious artefacts. Redact or tokenise sensitive fields before they reach an embedding model or an external service where required. Keep a record of the cleaning rules, since changing them changes the text that gets embedded and may require re-indexing.
This stage is where much of the hidden value is.
Attach a minimum set of fields to every chunk: stable document and chunk IDs, source path, created and modified dates, document type, owner, and access attributes. Good metadata lets retrieval filter and rank sensibly. It also records relationships between sections, so retrieval behaves more like navigating a document than searching it.
Chunking decisions affect answer quality directly. Structure-aware chunking, which respects headings, lists, and table boundaries, is usually the best first choice for enterprise documents, with each chunk covering one topic. Treat chunking as a document-specific engineering decision rather than a fixed character count. The retrieval strategy itself depends on the approach you pick; see fine-tuning vs RAG for how that decision is made.
Add checks that fail loudly: expected fields present, date ranges plausible, no empty chunks, no sudden drops in document counts, no schema changes from upstream. Treat the pipeline's own outputs as something to test, not trust.
Carry access attributes into the index and apply deterministic filters whenever a user asks a question, so people only retrieve what they are allowed to see. Test awkward cases such as shared folders and nested groups. Treat retrieved text as untrusted input, because documents can contain instructions that try to hijack the model. These concerns overlap with AI governance for forward deployed engineers.
Full rebuilds are slow and costly. Prefer incremental sync: use a reliable last-modified marker where one exists and content hashing where it does not. Treat a change of embedding model as a versioned migration with a controlled cutover rather than a quiet swap. Log the raw query, applied filters, and retrieved chunk IDs in rank order, so you can trace any bad answer back to the data that caused it.
You can't judge a pipeline by eye. Build a golden set: a collection of real questions with expected source documents and, where possible, expected answers. Then evaluate separately:
Separating the layers tells you where to fix things. Testing should also continue after launch, since data drifts and documents change. Fix data quality before tuning prompts; prompt tuning on noisy data tends to compound the problem.
A mid-sized insurer wants an assistant that answers staff questions about claims procedures. The procedures live in a document management system, a shared drive, and a legacy intranet. Many are scanned PDFs. Several have drafts and superseded versions sitting beside current ones.
The FDE begins by interviewing claims handlers and discovers that two documents are treated as authoritative and the rest are historical. The pipeline ingests all three sources with their IDs and folder permissions. Scans go through OCR, and a human reviews a sample of tables. Duplicates are collapsed, superseded versions are tagged with an effective-to date, and only current versions are returned by default. Each chunk carries source, version, owner, and access group. A golden set of fifty real staff questions is built from help-desk tickets, and failures are sorted by layer: parsing problems, a missing document, a conflicting version. Nightly incremental syncs keep the index current, and an alert fires if the document count drops sharply.
The assistant ends up more accurate not because the model changed, but because the pipeline stopped feeding it contradictions.
This work sits at the intersection of data engineering and applied AI, which is why many strong FDEs come from data backgrounds; see data engineer to forward deployed engineer for that path. Domain experience helps too: legacy-heavy settings such as AI in manufacturing and sensitive-data settings such as forward deployed engineering in healthcare AI are where these pipeline skills are tested hardest.
An AI data pipeline is the set of automated steps that collects data from source systems, parses and cleans it, enriches it with metadata, and delivers it to an AI system in a form that stays current and respects access rules.
Often because of the data, not the model. Common causes include unparseable scans, duplicate or outdated documents, poor chunking, missing metadata, and lost permissions. Debugging bottom-up, starting from the data layer, usually finds the cause faster.
Detect exact and near-duplicates, decide which version is authoritative, mark superseded versions with effective dates, and prefer the current version at query time. Record conflict rules so the behaviour is explainable.
Capture access attributes at ingestion, store them with each chunk, and apply deterministic filters at query time so users only retrieve content they can already see. Test edge cases such as shared folders and nested groups.
Build a golden set of real questions with expected sources, then evaluate parsing, retrieval, generation, and end-to-end behaviour separately. Continue testing after launch, since sources and documents change.
They map where the data really lives, ingest it with identifiers and permissions, parse and clean it, resolve duplicates and conflicts, set up evaluation, and keep it updated, working closely with the people who use it.
The world is hiring - and this Academy prepares you for it.